When the Gate Stays Closed: Empirical Evidence of Near-Zero Cross-Sectional Predictability in Large-Cap NASDAQ Equities Using an IC-Gated Machine Learning Framework
A deployment gate for financial ML, and the discipline to report that it stayed closed.
The discovery in one figure
Swipe to see the whole figure
The paper in five minutes
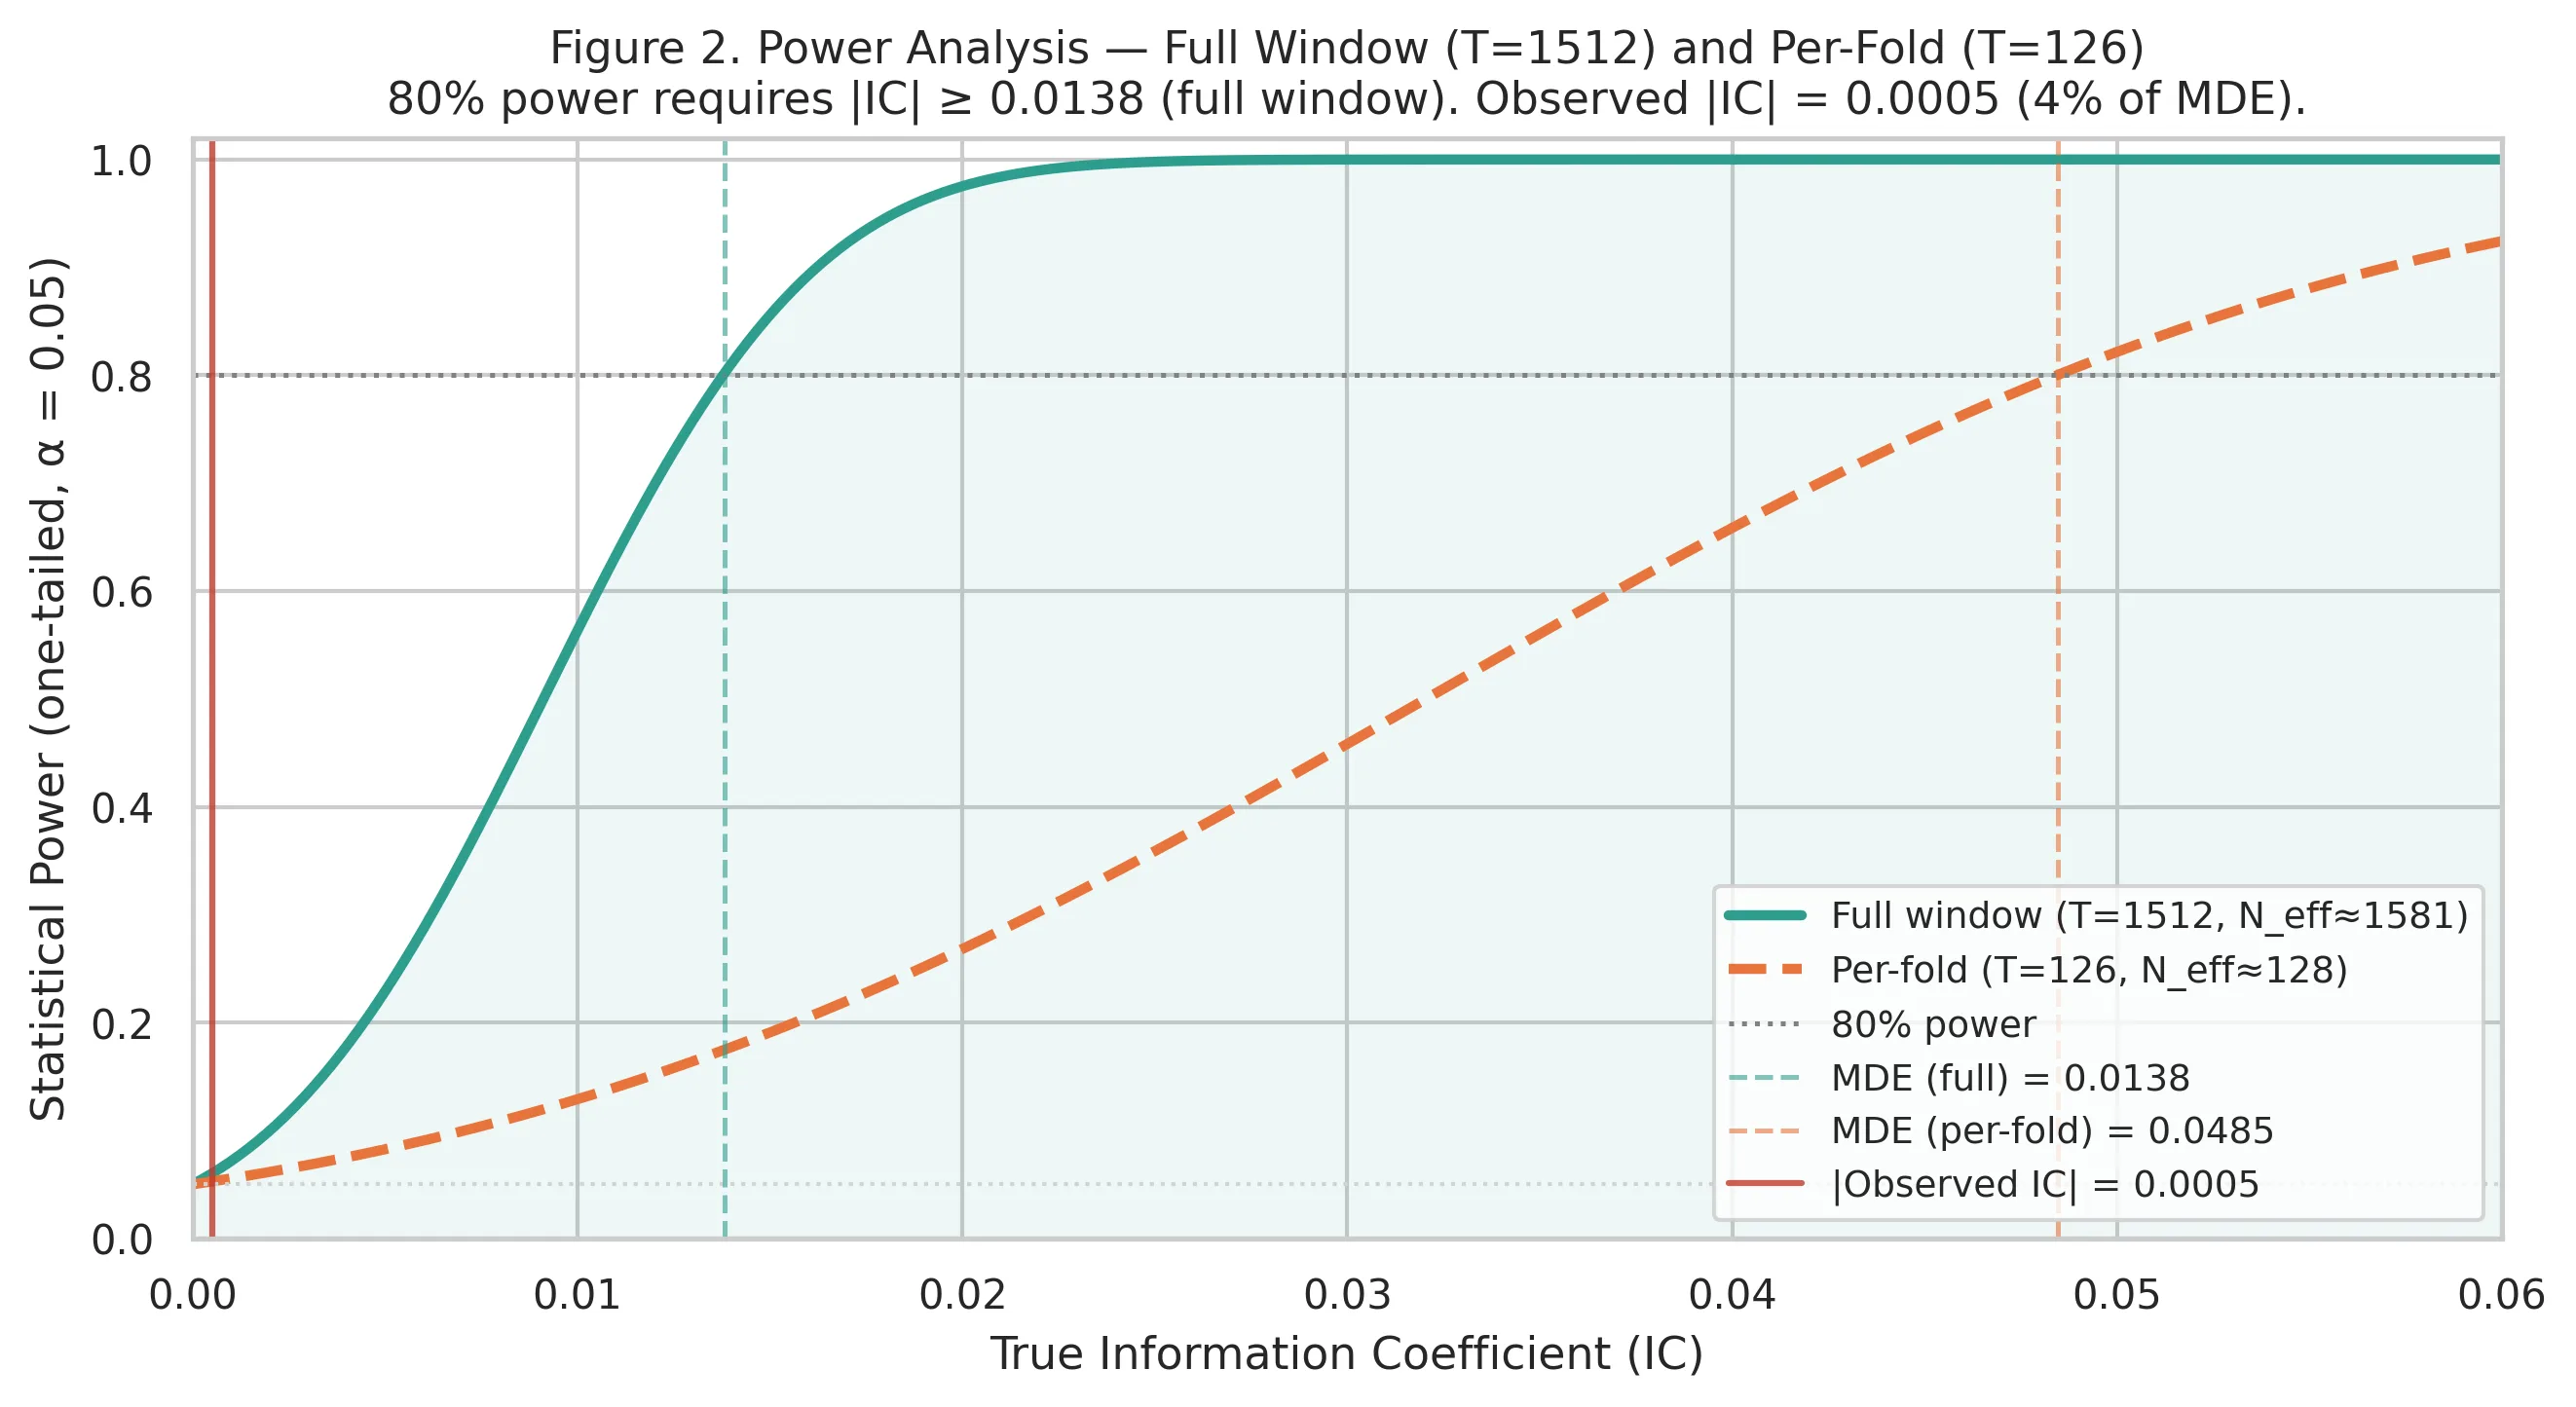
Most trading-model papers report wins. This one builds the exam a model must pass before it is allowed to trade real money, and then reports that its own model failed that exam twelve times out of twelve. That is the contribution: a statistical gate that separates “looks profitable in a backtest” from “provable skill”. A naive statistical test would have green-lit a skill-less model 11.8% of the time; the full gate never did. And the model’s probability estimates stayed well calibrated even though it had no predictive skill, which is the proof that a well-calibrated model is not the same as a deployable one.
The research question
Can a financial ML model prove cross-sectional predictive skill before deployment, and what should happen when it cannot?
How it works
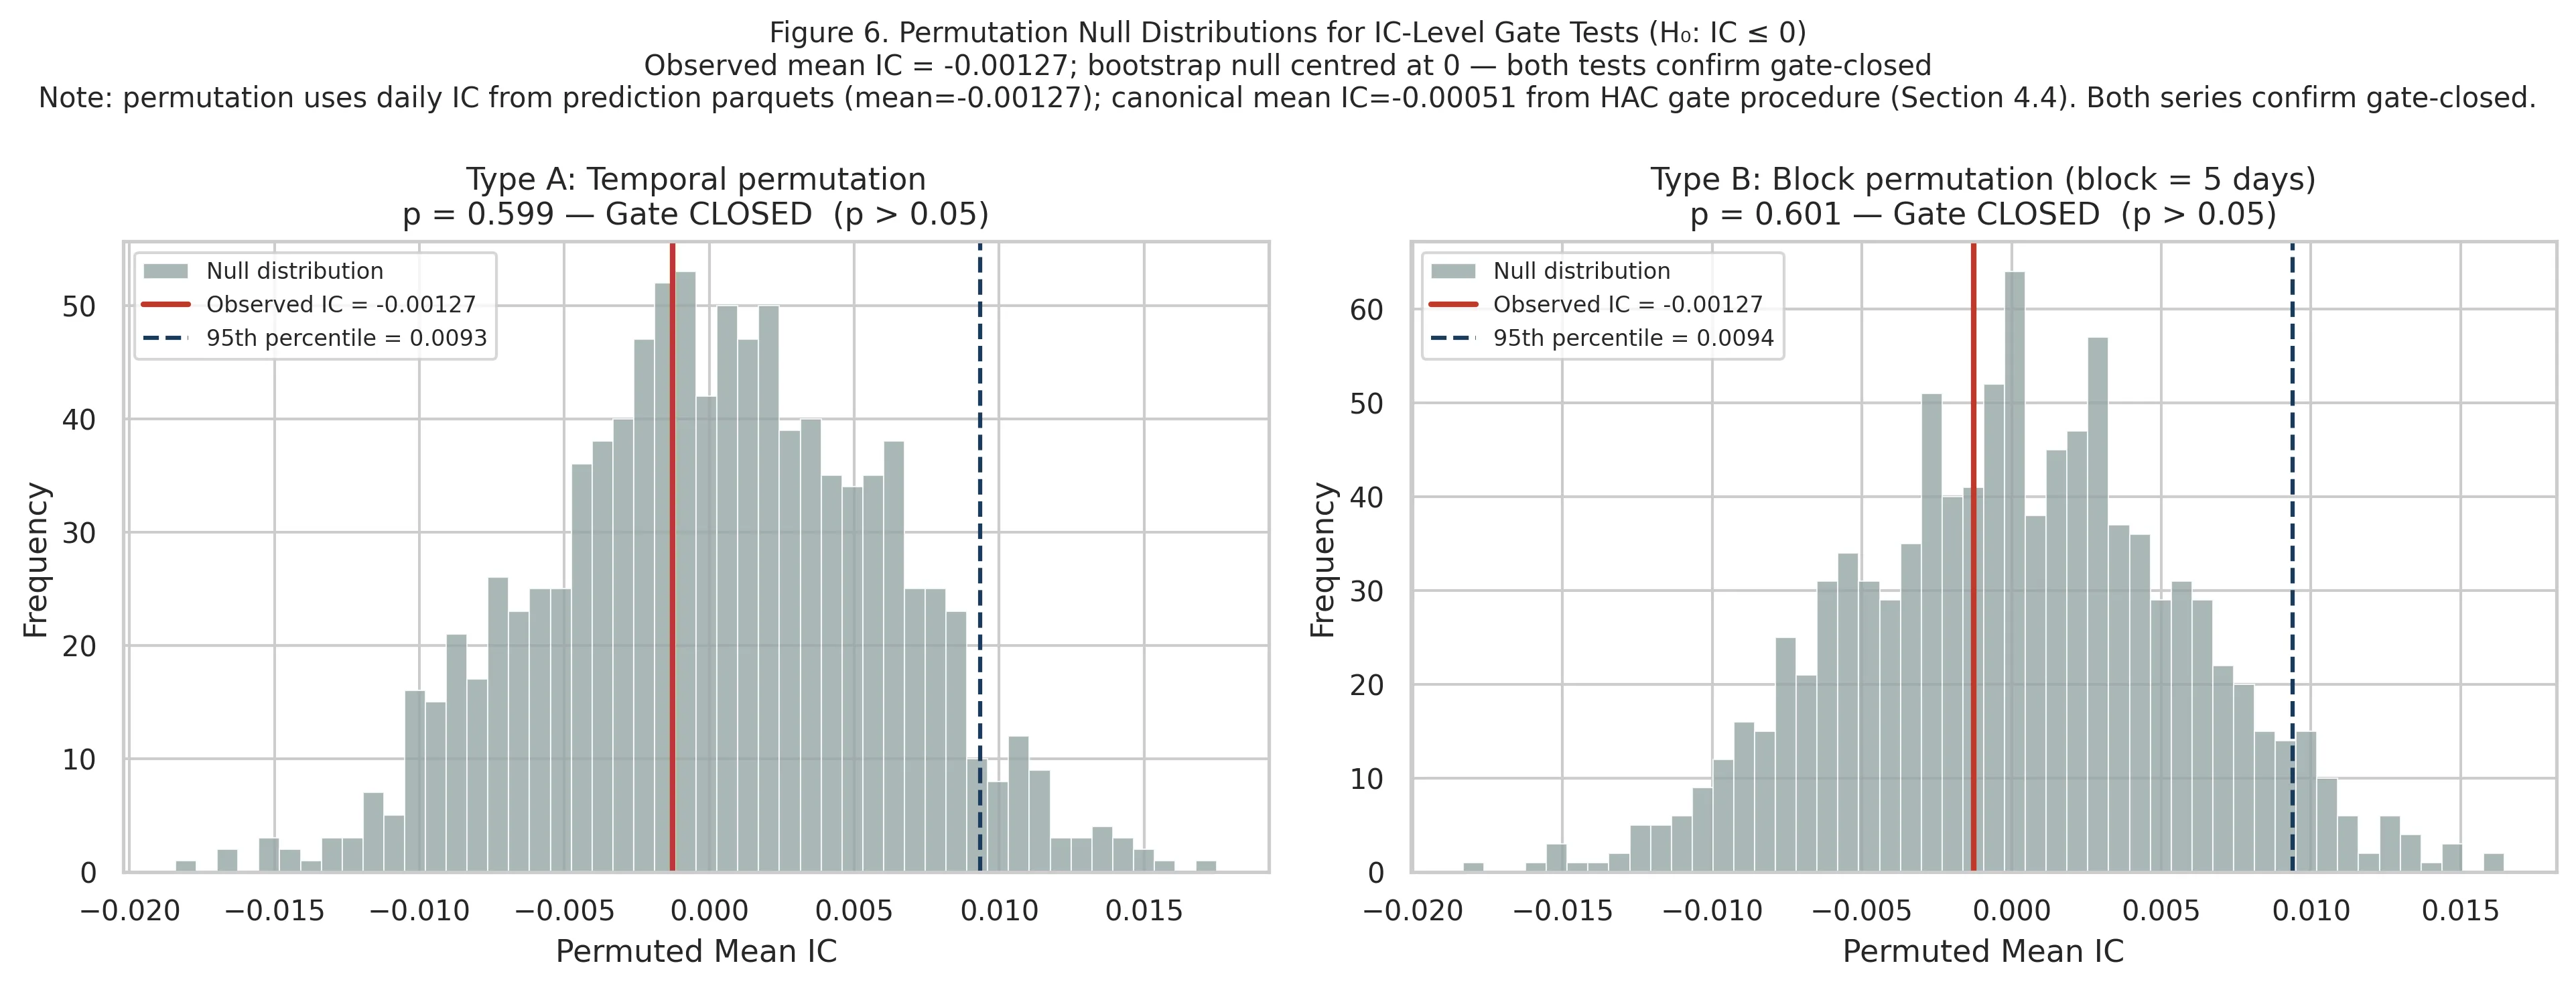
IC-Gated Deployment Framework: a two-stage statistical gate (Newey-West HAC t-test on daily information coefficients plus permutation confirmation) over 12 expanding walk-forward folds and 1,512 out-of-sample days, with isotonic calibration, a momentum positive control and a Nifty 50 cross-market replication.
- 01Build honestly49 strictly causal features, 30 NASDAQ stocks, no lookahead
- 02Walk forward12 expanding-window folds, 1,512 out-of-sample days, 2-day embargo
- 03Measure skilldaily information coefficient → Newey-West HAC t-test
- 04Confirm by permutationboth stages must pass: if either fails, no deployment
- 05Report the nullgate closed 0/12; calibration excellent anyway (ECE < 0.025)
Experimental results
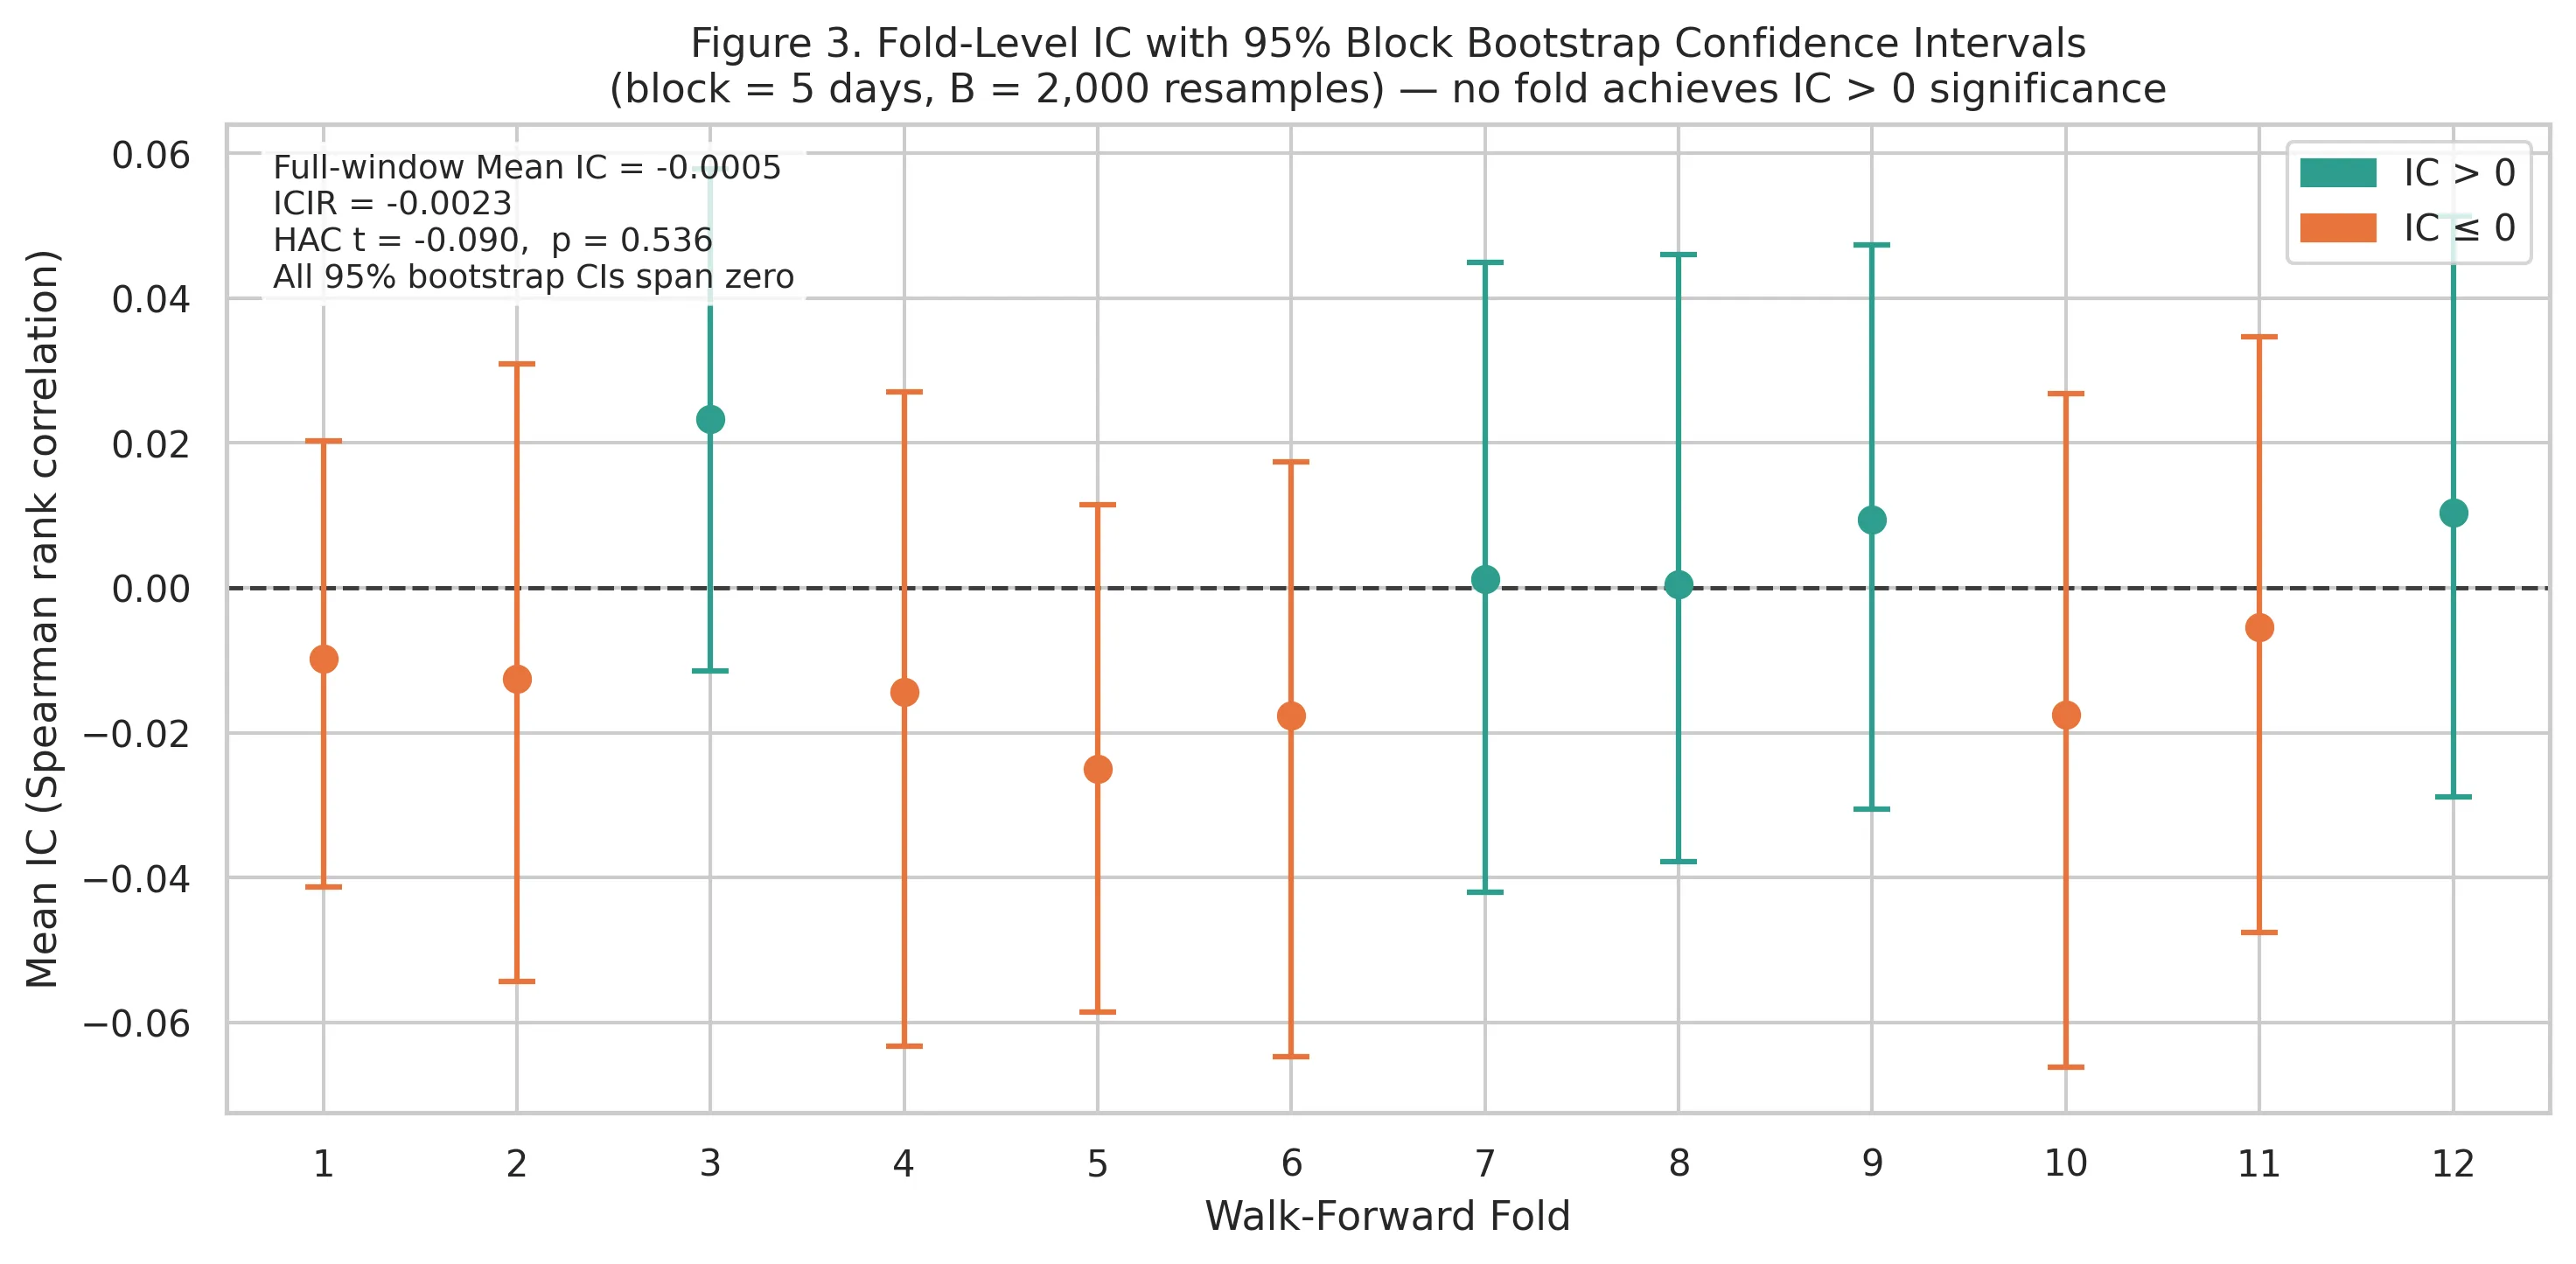
Mean IC −0.0005 (HAC t = −0.09, p = 0.536); the gate opens in 0 of 12 folds. Calibration stays excellent (ECE < 0.025) despite zero discrimination: calibration quality is not deployment readiness. The naive t-test alternative gives false positives 11.8% of the time, the full gate 0.0%. The Nifty 50 replication is also gate-closed.
11.8%0.0%Simulated null (no real signal): the naive test deploys anyway; the gate never does.
- 0 / 12folds passing the deployment gate
- < 0.025ECE while IC ≈ 0: calibration ≠ readiness
- 11.8% → 0%false-positive rate, naive test → ICGDF
Figures from the paper
Figures as generated by the paper’s own analysis pipeline.
What this changes
An honest null result engineered as methodology: the same audit-first stance the program applies to healthcare and lending, applied to the temptation-rich domain of trading.
Citation
Working paper. The public version is linked above. Reach me at rajveerpall04@gmail.com.